Audit steps
How can you independently audit what AI models say, and keep evidence others can check?
Run the same documented questions against several models, repeatedly, and keep every answer. Each step below leaves a record, so a reviewer can follow the audit from question to number.
| 1. Fix the questions | Questions in the words real people use, held unchanged between waves. Kept: the question set for each wave. |
|---|---|
| 2. Define the audiences | Each question asked for each audience segment, plus a baseline with no audience. Kept: the segments and the AI-generated audience members each question was asked as. |
| 3. Query several models live | Each question is asked of several AI models, with web search on where supported. Kept: which model gave each response, and when. |
| 4. Repeat each question | Several draws per question, model and audience. Kept: the number of responses behind every rate. |
| 5. Extract mentions and sources | Entities, order, sentiment and cited web pages read from each answer. Kept: the extraction beside the raw response. |
| 6. Report rates that trace back | The mentions behind each organisation’s figures open onto the responses they came from. Kept: every raw response, readable in the app and downloadable as CSV or JSON. |
Principle
AI answers are a distribution, not a ranking
Ask an AI model the same buying question twice and you can get two different answers: a different first recommendation, a different shortlist, different sources. That is not a bug in the measurement, it is how these systems work. Sampling randomness, live retrieval, and continuous model updates all move the answer between draws.
The consequence is simple: any tool that reports "you rank 3rd in ChatGPT" from a single query is reporting one roll of the dice as if it were a constant. There is no stable list to hold a position in. The honest question is not "what is my rank" but "how often am I named, how prominently, described how, for which audience, on which model".
Everything llmeknow reports is built on that framing: rates over repeated samples, compared across models, audiences, and time.
Step 01
Questions use the words real people use
Each study starts from questions phrased the way a real person asks them: "which medical aid is best value for a young family?", not "medical aid comparison". Question sets are generated from a description of the market and can be edited before anything runs. Once a study is live, the question set is held stable between waves, because changing the questionnaire mid-study means measuring your questions instead of the market.
Step 02
The audience is part of the instrument
AI models tailor answers to the person asking. The same insurance question from a student and from a retiree produces different recommendations and different reasoning. Measuring with a single anonymous prompt hides exactly the variation that matters commercially.
llmeknow generates audience segments for the market and asks every question in the context of individuals from each segment, alongside a baseline run with no audience context. The gap between the baseline answers and the answers each segment gets is treated as signal, not noise.
Step 03
Multiple models, queried live, repeatedly
Every question runs against multiple major AI models, with live web search enabled where the model supports it. Models disagree with each other, so single-model tracking measures one model’s opinion, not AI presence.
Because single draws are unstable, each question can be repeated several times per model and audience context within a wave. Repetition is what turns "the model said X once" into "the model says X in 7 out of 10 draws", which is the level at which the numbers start meaning something.
Step 04
Mentions and cited sources are extracted separately
From every response, llmeknow extracts which entities were mentioned, in what order, described with which attributes and sentiment. Variant names are grouped into a single clean entity so a brand and its abbreviation count as one.
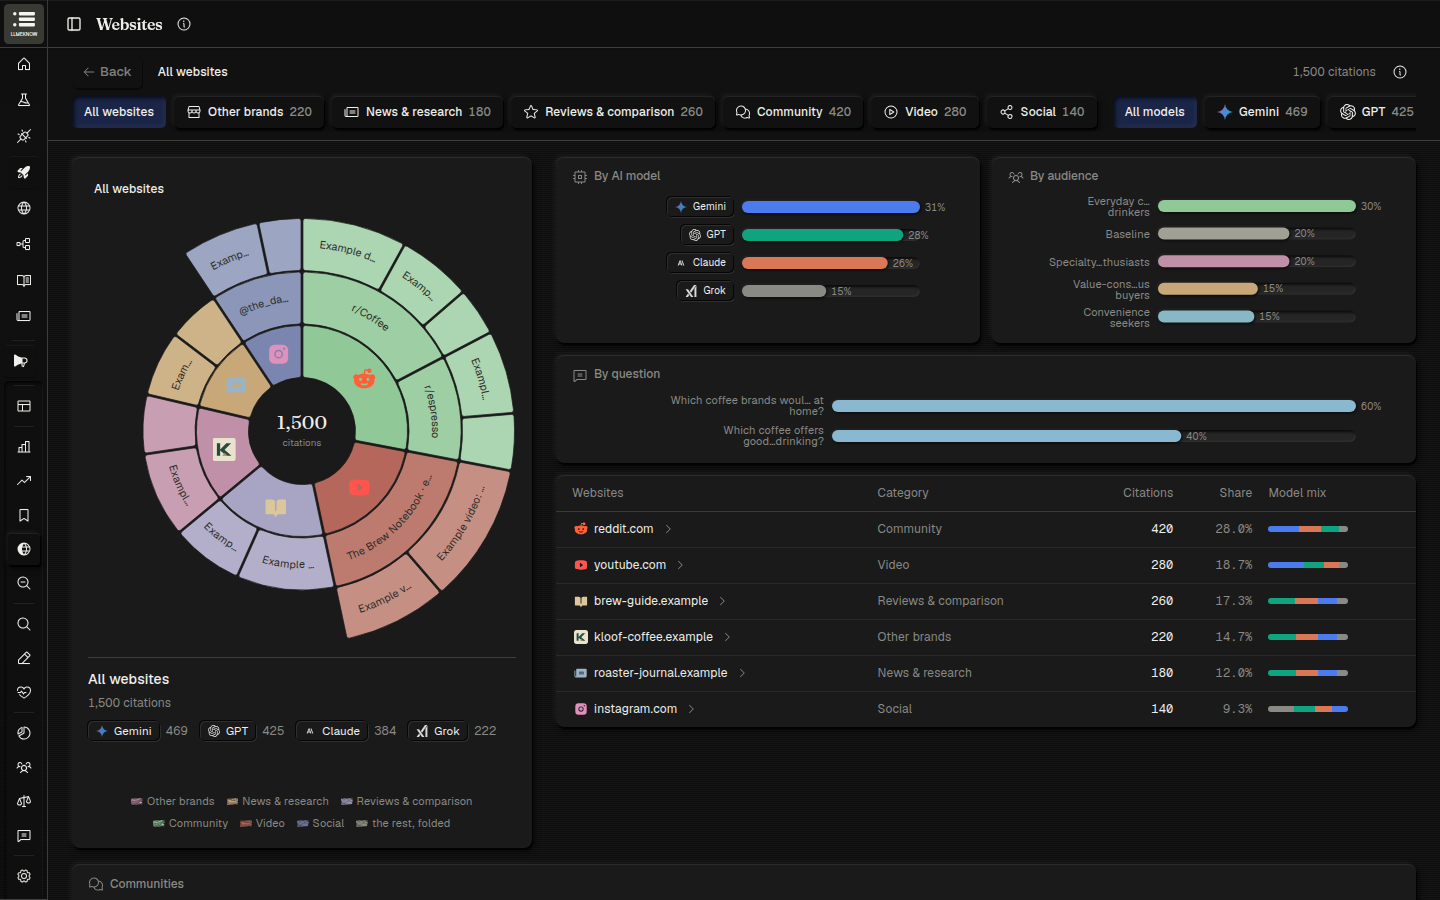
Separately, it records which web sources the models cited while answering. Being cited as a source and being recommended in the answer are different things, and they diverge more than most people expect. The cited-source map also shows where models get their story about a market, which is where the actionable work usually lives.
Step 05
Reported as rates, with the evidence kept
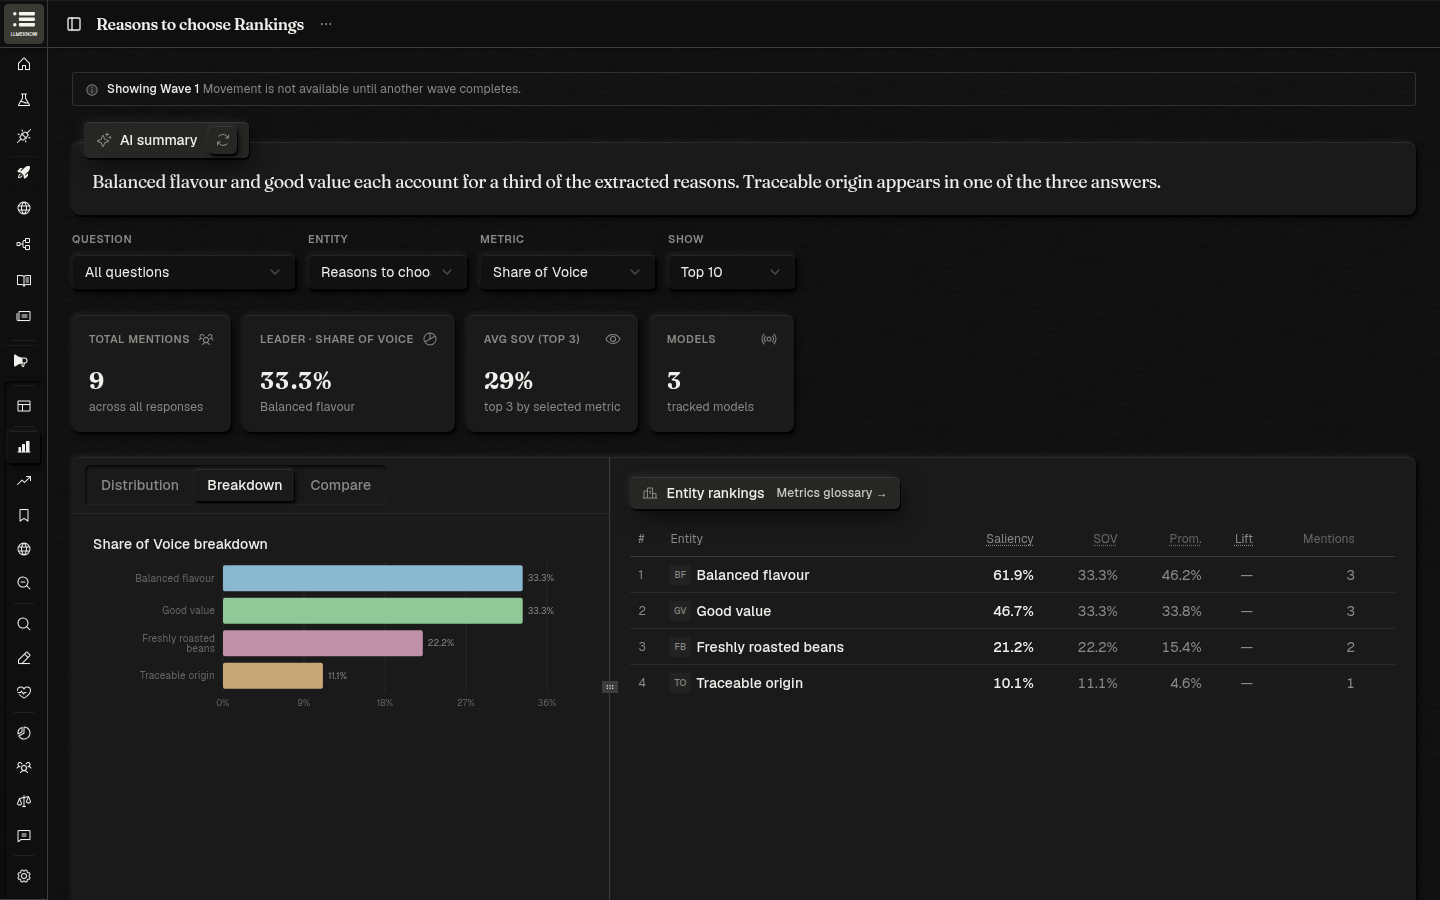
Results are reported as rates across all runs: how often each entity is mentioned, how often it is named first, its share of voice, how it is characterised, per model and per segment. Alongside the rates, llmeknow measures answer stability itself: how much the answers to a question move between repeated draws, so a volatile, contested market is visible as exactly that.
Every raw response is kept and inspectable. When a chart says a model recommends a competitor to a specific segment, you can open the actual responses behind that number and read them.
Honesty
The limits of any AI perception measurement
Some things no tool in this category can honestly promise, so we state them instead:
- Consumer apps are personalised. A logged-in user with chat history can get different answers than any controlled measurement. llmeknow measures a consistent, repeatable instrument so movement between waves is real, not an artefact of one user’s history.
- Models update continuously. Part of any change between waves is the model changing, not the market. Repeating a stable question set is what separates trend from noise.
- Point estimates carry uncertainty. A rate measured from a handful of draws has a wide margin. More repetitions narrow it; a single draw is directional at best.
- No tool can see the exact prompts real people type. Question sets written in their words approximate them; self-reported attribution and referral traffic complete the picture on your side.
Position
What llmeknow deliberately does not do
No single-query "rank" presented as a stable fact. No invented precision without the run counts behind it. No tricks sold as optimisation: hidden prompt text, stuffed meta tags, and mass-generated pages do not change what models say and can hurt the sites that try them.
The way a brand improves its AI presence is unglamorous: accurate, current information in the places models actually read and cite. The measurement exists to show where that work will pay off, and then to verify whether it did.