The problem
AI visibility research needs the same rigour as any other research programme
Enterprise marketing and research teams already run structured audience research. AI visibility deserves the same standard: defined segments, repeatable measurement, and evidence you can trace back to a source, not a single opaque score.
llmeknow treats AI perception as a research problem: your market’s actual questions, run across every major model, in the context of the audience segments you already use.
Coverage
Every major model, tracked as a programme, not a one-off check
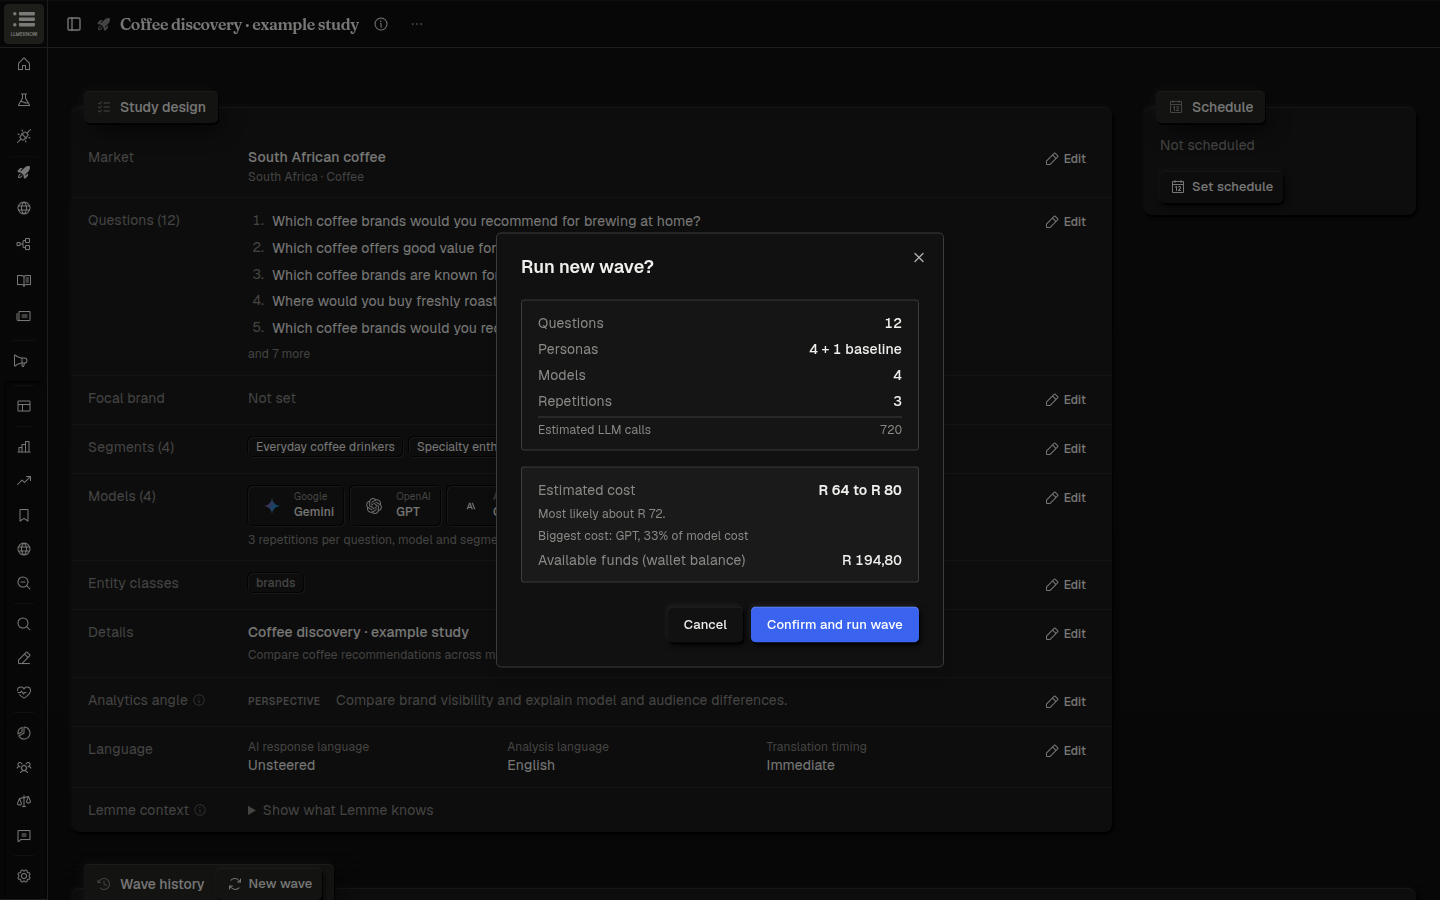
llmeknow runs your tracked questions across ChatGPT, Claude, Gemini, Grok, DeepSeek, and Kimi, with new models added as they gain adoption. Studies run as scheduled waves, so results are comparable over time rather than a single snapshot.
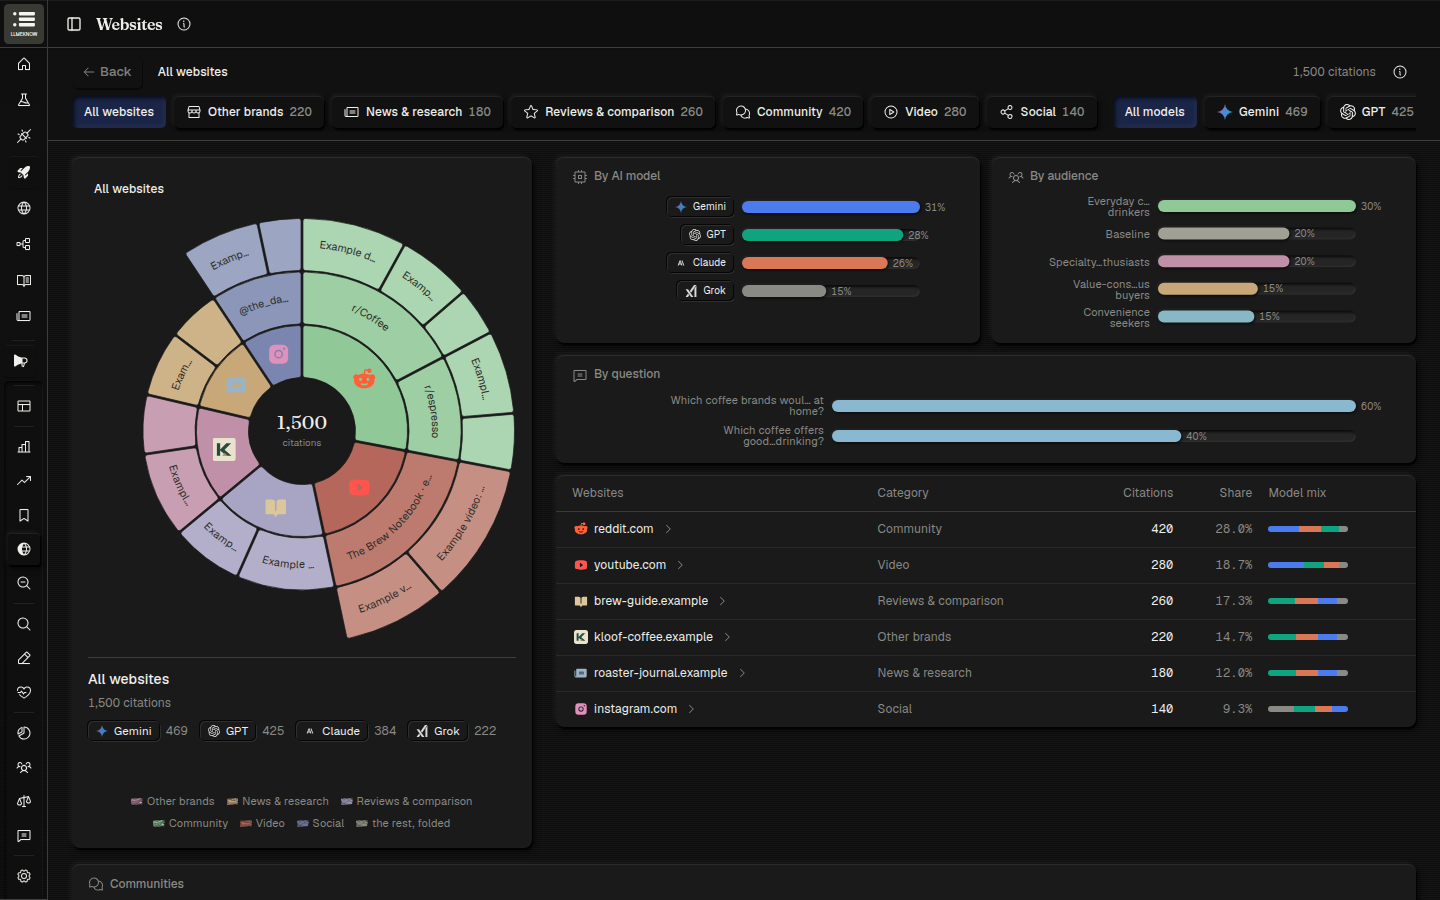
Every response is stored and inspectable, with entity mentions, sources, and citations attached, so a finding always traces back to the exact text that produced it.
Segmentation
Your segmentation, not a generic template
If your team already has an audience segmentation framework, llmeknow builds around it rather than replacing it with a generic demographic template. Segment-level results sit alongside a no-segment baseline, so you can see exactly where AI’s account of your brand diverges by audience.
Entity tracking
You define what counts as a mention
Track more than brand names: attributes, features, pain points, services, or any custom entity category your research requires. llmeknow groups variant names into a single clean entity automatically and tracks each one across every wave.